
Cheerful — AI Gift Recommendation for iOS
Role: Co-founder and Principal Application Developer, NeuNet
Timeline: Nov 2023 – Aug 2025
Stack: Swift, SwiftUI, Node.js, Express, TypeScript, MongoDB, AWS, Firebase, OpenAI API, MCP

Summary
Cheerful turned five inputs — recipient’s name, age and gender, interests, budget, and occasion date — into twelve specific, purchasable gift suggestions. No account, no signup friction. At peak it served more than 15,000 users in the US on total infrastructure of under $400/month of infrastructure.
It went through three architectures in under two years. It launched as a pure LLM app offering gift ideas and the reasoning behind them. It then gained a source of truth, cross-matching every idea against Amazon’s catalog so users saw real products with real prices. Finally it became agentic, with the model querying the catalog itself through an MCP tool. Each move traded some simplicity for reliability, and each was a deliberate decision about cost, trust, and what users actually needed.
Around that evolution sat the rest of the engineering: output that parsed every time, latency short enough to hold attention, cost low enough to serve anonymous users at consumer scale, and stability through national TV coverage and holiday peaks.
Context and constraints
Three product decisions set the engineering constraints:
No registration. Users opened the app and got results immediately. Good for conversion, but a bit hostile for engineering: every anonymous user could trigger an expensive generative call with no account to attribute it to, no user ID to rate-limit against, and nowhere server-side to persist their lists.

Twelve results, not one. Twelve suggestions give the user something to browse and hide individual misses, but it multiplies the cost of every request and the surface area for malformed or repetitive output.

A hard budget ceiling. Users picked a spending limit. A language model can suggest ideas in a price range, but it can’t know what anything costs today. That constraint is what eventually pushed the product from model-generated ideas to a real source of truth.
Problem 1: Reliable structured output
Every version depended on the model returning suggestions as JSON the client could render. In a mobile client, a malformed response isn’t a logged warning; it’s a blank screen after a user waited.
Early on this meant parsing, exception handling, and retries, which ran an 8% error rate and cost real money in redundant calls. As OpenAI shipped schema enforcement and strict mode, I moved validation upstream, and malformed-response retries stopped being a line item in the budget.
Repetition was the harder problem, and the only quality complaint users consistently raised. A narrow enough recipient profile could exhaust the model’s distinct ideas well before twelve. I capped result counts, validated each generation against suggestions already returned, and let the result set end gracefully rather than pad it with near-duplicates.
Problem 2: From model ideas to real products
This is the problem that shaped the architecture, and it was solved in three stages.
Stage 1: ideas, not products. The MVP was deliberately simple. The app sent the recipient profile to our backend, the backend wrapped it in a prompt, and the model returned suggestions as JSON from its own knowledge. No prices, no images. Tapping a suggestion opened an Amazon search for that product name. The value proposition was the ideas themselves and the reasoning behind each one — why this gift for this person. That scope made hallucinations tolerable: a plausible but imperfect idea still landed on a search page full of real alternatives. It also meant the product couldn’t honor the budget reliably.
Stage 2: a source of truth, with the model kept at arm’s length. To show real products, I added Amazon’s product search API as a step after generation. The model produced ideas; the backend cross-matched each one against the catalog, pulled real listings with prices, images, and product details, and returned only that sanitized list. Those results — snapshots — were stored for reuse. The model’s involvement ended when generation did.

That separation was deliberate. The search API carried its own cost and rate limits, and I didn’t trust the model to call a paid API responsibly without guardrails. Keeping retrieval in deterministic backend code gave us full control over when and how often the API was called.
The known tradeoff was freshness: snapshots could drift from live prices. At our scale this stayed minor. Every suggestion linked through to the live Amazon listing, where users saw the current price before buying, and a nightly job refreshed stored snapshots against the catalog.
Stage 3: agentic retrieval. Once the pipeline was stable and costs were understood, I built an MCP server exposing a catalog-search tool and let the model query it directly, searching on keywords and categories it derived from the recipient profile. That cut the number of steps between prompt and results, and replaced after-the-fact matching of the model’s output with retrieval the model drove itself.
Problem 3: Latency
We launched at a 60-second average with a p90 close to three minutes. Smooth animations and rotating status messages made the wait tolerable, but they were a bandage.
First attempt: cut the initial fetch from twelve items to eight. Marginal gain, and it broke the layout on larger screens. Second attempt worked better — start the request earlier in the recipient-creation flow, since fields like the occasion date aren’t needed to generate suggestions. That cut waiting time roughly 25%.
As images and infinite scroll increased API demand, flow changes stopped being enough. The fix was architectural: scale ECS horizontally and vertically, move to higher-tier MongoDB nodes, and — most importantly — query a centralized store of every snapshot before touching any third party. Snapshots were uniquely identifiable and cheap to keep, so the store compounded: every new user diversified the pool for everyone after them.
End state: 75% latency reduction, p90 at 45 seconds.
Problem 4: Anonymous users on an expensive endpoint
No accounts meant no user ID to rate-limit against and nowhere to store gift lists. We kept it that way on purpose, to let casual users in without an onboarding wall, but it raised three questions: how to attribute data to a user, how to stop abuse, and what happens on reinstall.
No account doesn’t mean no identity. I used Firebase anonymous authentication to assign a user ID scoped to the device and install, with no personal data collected. Every action tied back to that ID, which made rate limits and access controls straightforward. It also let us persist non-sensitive data — recipients, gift lists, events — and restore it automatically on reinstall. A delete-and-start-fresh option came later.
Problem 5: Cutting operating cost
We set a $500/month ceiling when we designed the platform. Costs came from OpenAI, Amazon’s search API, cloud infrastructure (Google Cloud, later AWS), and MongoDB Atlas — all consumption-based and hard to forecast. Rate limits and caching were in place from the start, mostly as insurance against going viral and waking up to a five-figure bill. It wasn’t enough: we ran over $650 in quiet months and past $1,000 during holidays.
Three things fixed it:
Backend efficiency. Profiling the request-handling and parsing paths turned up real waste. Strict schema validation cut JSON parsing retries 12%, and refactoring the endpoints and trimming the response structure reduced per-generation load.
Caching. Product suggestions repeat far more than you’d expect — a given gift fits a wide range of recipients. On-device caching plus the shared snapshot store cut Amazon API calls roughly 45%.
Model economics. OpenAI’s prices fell steadily as new models shipped. In 2025 I moved our workload to an older, more cost-efficient OpenAI model that was good enough for gift suggestions at a fraction of the per-token cost.
Together with prompt optimization and a move to cheaper storage, monthly infrastructure went from $650 to under $400 — a 38% reduction.
Problem 6: Traffic spikes and seasonality
Cheerful was covered by Yahoo News, NBC Los Angeles, FOX 26 Houston, Good Day Alabama, and Good Things Utah. A segment brought 400–600 new downloads in a day, and the scaling and caching work absorbed it. Traffic correlated with revenue, so peaks were never the worry.
The off-season was more interesting. Traffic there didn’t convert, because our revenue depended on a 24-hour purchase window to earn commission. Users browsed, left, and bought later, outside the window. We paid for every generation and earned nothing back.
The fix was a conversion problem, not an infrastructure one: occasion reminders, incentives for prompt purchase, transparency about how the app stays free, and a more aggressive notification cycle tailored to each recipient’s occasion type. Purchase-after-search rose from 13% to 24%.
Architecture
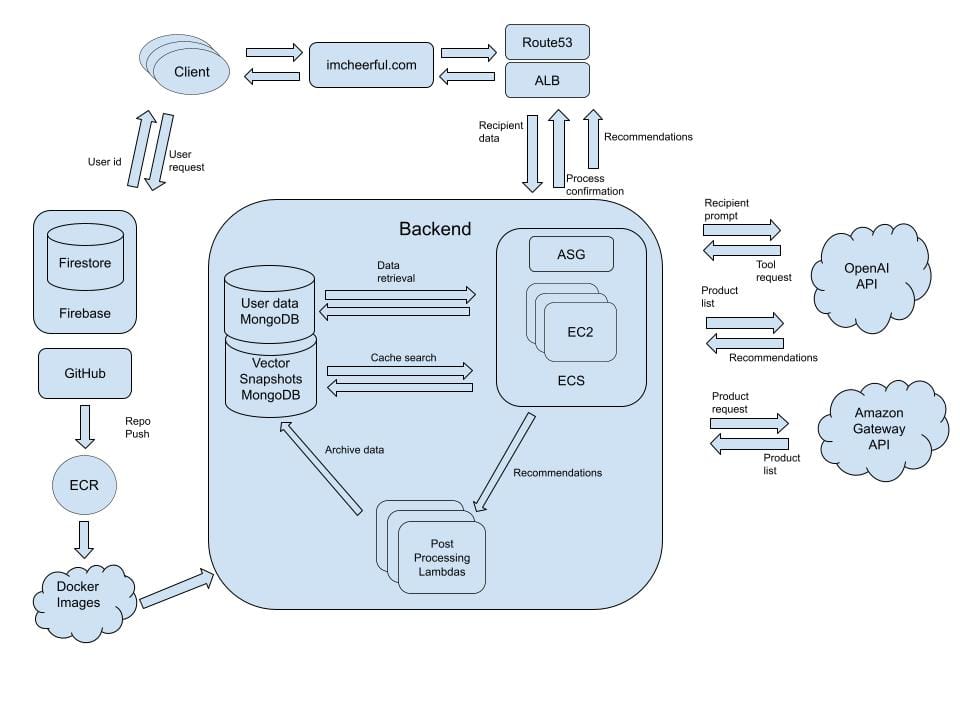
A request runs: client → Route 53 → ALB → Node.js tasks on ECS, backed by an Auto Scaling Group of EC2 instances that scales on CloudWatch CPU metrics. The service first checks stored snapshots for a match. On a miss, it sends the recipient prompt to the OpenAI API; the model issues tool requests to our MCP server, which queries Amazon’s catalog and returns real listings; the model returns ranked recommendations. Post-processing Lambdas normalize the results and archive them as snapshots for future requests. MongoDB holds user data; Firebase issues the anonymous device identity. Deployment runs GitHub → ECR → ECS.
What I’d do differently
Instrument cost per session from day one, and build the snapshot store first. We discovered how far off our estimates were late, and we didn’t understand our revenue model’s failure mode until we lived through an off-season. The snapshot store ended up solving latency, cost, and API load at once; designing the data flow around it from the start would have saved real money.
Build evaluation from the start. We judged quality by the absence of complaints. That caught the one problem users told us about — repetition — and nothing subtler. A fixed set of test recipient profiles, scored on every prompt or model change, would have turned each architecture change and the eventual model switch into measured decisions rather than judgment calls.
Use the embeddings we were already storing. We stored snapshots as vectors in MongoDB but only ever used it as fast storage. Semantic similarity would have let us match new requests to existing snapshots far more often, and ground the model in our own catalog of proven suggestions.
Treat price freshness as a requirement. A nightly refresh plus a click-through to the live listing was enough at our scale. At larger scale, I’d re-check price at display time for any snapshot older than a set window.
Outcomes
Over 15,000 users at peak, purchasing hundreds of items a week. Three architectures in under two years, from model-only to catalog-grounded to agentic. Operating cost down 38% ($650 → under $400/month), p90 latency down 75% (~3 minutes → 45 seconds), purchase-after-search conversion up from 13% to 24%. Coverage across five national and regional outlets.
NeuNet wound down in 2025 and ceased all operations, including the Cheerful app and website.